After theFrontier
- Five minutes, one idea: the frontier model is no longer the default answer for production AI.
- The beacon on the horizon is the frontier. The lights in the foreground are where the action is moving.
Every new frontier model felt like a power-up.
Coding and app building still run on Claude and OpenAI. A $100/month subscription buys far more tokens than it costs.
Production work is moving to open, specialised and fine-tuned models, because the API bill hurts and most tasks don't need that much power.
53% → 45% frontier share of US corporate AI tokens, Aug → Sep
- When a new frontier model came out, it felt like a huge power-up. The only way to get more value was to use the biggest model.
- That's still true for development. The subscriptions are great value.
- Ramp's AI Index: frontier labs' share of US corporate tokens fell from a 53% peak in August to 45% in September. ETR: open-weight models now carry 34% of enterprise tokens, up from 23% a year ago.
- For production workloads, people are realising they don't need that much power. They're cutting API spend with open-source and in-house training.
One job.
Done fast.
Done cheap.
- Yesterday (Oct 13) OpenRouter listed ScaleDown's "constrained decoding models": Extract, Summarize, Classify. Each does one job.
- Extract takes text, images or PDFs and returns clean JSON with confidence scores and citations. That's the OCR-to-structured-data use case.
- About 4–5 cents per million input tokens, output free. ScaleDown claims 200x faster and 467x cheaper than frontier APIs (vendor claim).
- Same week: Microsoft-Decision-1, Perplexity Decider, Mercury Decide. You don't need a sledgehammer for a screw.
Small model.
Your data.
Your hardware.
- Unsloth ~78K GitHub stars, shipping almost daily · train a decision model on 4GB VRAM
- Qwen3.8-27B 7.2M downloads last month · 1,400+ community quantisations
- A huge community has grown around the tooling for specialising models. Unsloth is the name everyone mentions.
- Coinbase (Brian Armstrong, Oct 11): fine-tuned open-weight Qwen3.5-9B on internal data for Onramp fraud screening. Beat Claude Opus 4.5 on precision, recall and dollar-weighted recall (+35 pts). p50 latency 0.68s vs 1.52s.
- Trained for under $100 on a single RTX PRO 6000 (per Coinbase's "Owning Intelligence" blog series). Staff get an internal skill: /fine-tune-and-serve-llm.
- Fun twist in their Part 2: newer frontier models did worse on this benchmark than older ones.
- Qwen3.8-27B is the community favourite base model. Unsloth just shipped "train your own Jev-style decision model".
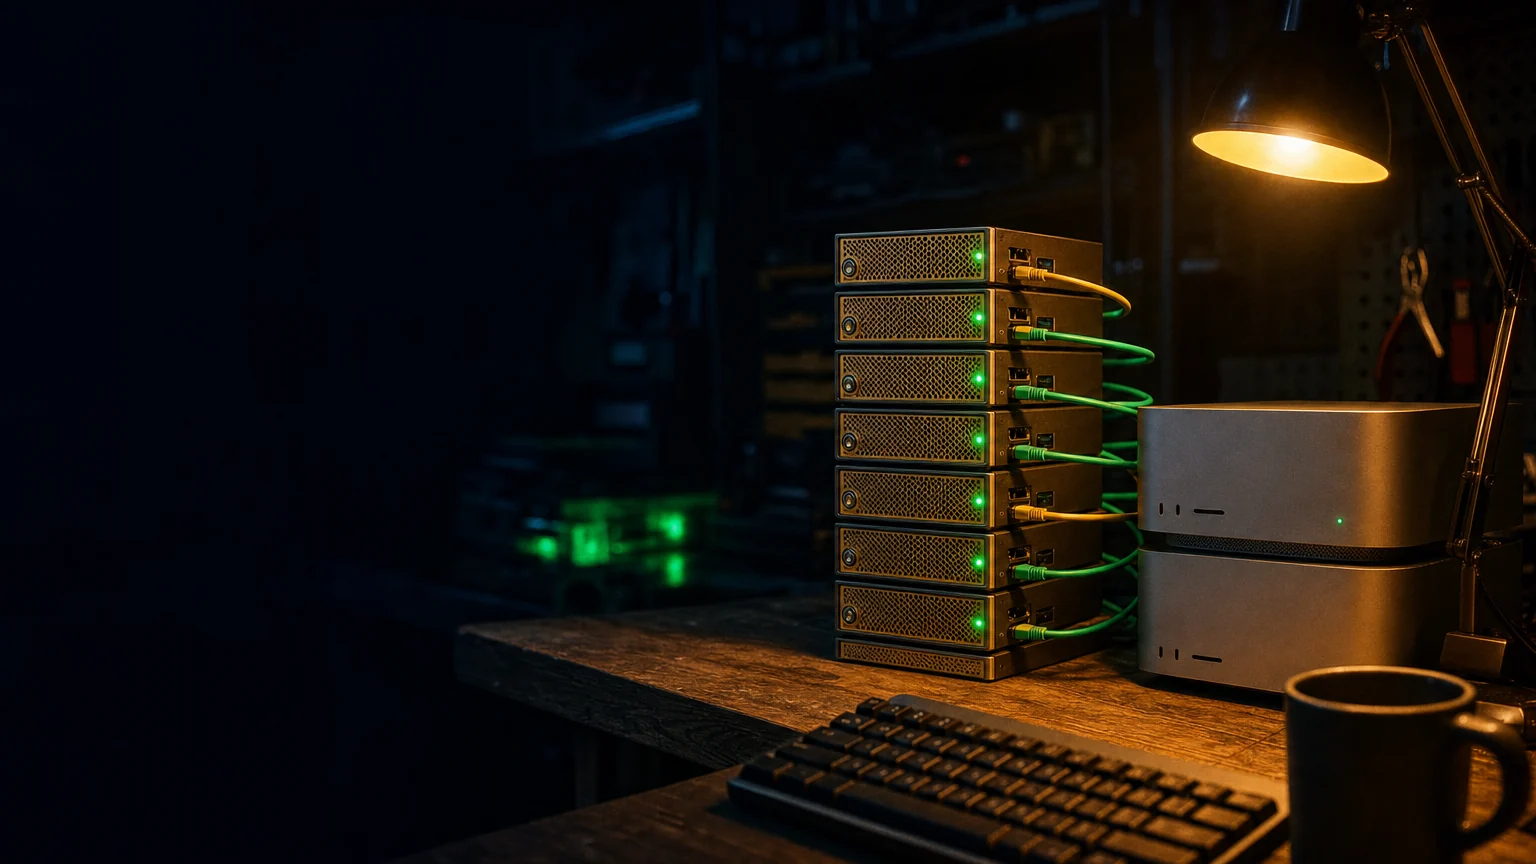
The rich hacker's playground.
Six DGX Sparks at $30–40K run a near-frontier open model at home. No payback yet, but the tuning tricks flow downstream.
- Right now local AI is the playground of wealthy programmers. It doesn't pay back financially, but it's a lot of fun.
- People with clusters of DGX Sparks and M5 Mac Studios are getting remarkable results.
- Matt Mastracci (@mmastrac): 6+ Sparks. His KindlingAI team wrote a from-scratch engine for GLM 5.3 full: 50 tok/s on code, 1,300 tok/s prefill on four Sparks. He's using GLM to make its own engine faster.
- His math: six Sparks, $30–40K today, to get off AI subscriptions. Expects ~$10–15K in 2–3 years.
- @sudoingX took DeepSeek V4.1 Flash from 39 to 103 tok/s on two Sparks in four days.
- Sparks are $6,950 now (memory shortage). M5 Ultra Mac Studio goes up to 512GB and clusters over Thunderbolt 5.
- Watch it anyway: these gains filter down and become commodity. And again, it's open-weights models winning.
Not every question needs an essay. Some need a verdict.
A decision model returns a choice and a confidence score. Input 4¢ per million tokens. Output free.
- Jev arrived and rocked everyone's world: a decision model, no charge for output tokens, a confidence score on every decision, and very fast.
- Then the copycats came, open and closed. Cloudflare shipped open-weights Clef 2 weeks later. OpenAI shipped its Decisions API 3 weeks later; per Fortune, it wasn't on their roadmap a month earlier.
- TypeSafe reportedly raised ~$870M at a $7.5B valuation (Bloomberg, Oct 9).
- Next-token LLMs are heavy-handed for classification, quick decisions and following a recipe. Expect more niches like this.
No dead time.
Stay at the wheel.
Next: fast enough, and the model stops writing code and renders the app itself, live, at 60fps.
- Something changes when there's no dead time between requests. You experiment more, try more things, and stop second-guessing your prompts. It just happens.
- People report what 1,000+ tok/s feels like, even on models that aren't the frontier leader. Who cares? You iterate your way past the limits while staying at the wheel.
- You don't pause your deep thinking on every prompt and hope your brain's cache doesn't empty, or that you don't get distracted.
- Data points: OpenAI's Codex-Spark on Cerebras ~1,000 tok/s (about 15x standard Codex). Cognition SWE-1.7 at 1,000 tok/s. Inception's Mercury 2.5 diffusion model ~1,100 tok/s. Taalas hardwired chips: 17,000 tok/s on Llama 8B. Opus-class models run around 65 tok/s.
- The wild end: code is use cases in a reusable format. If models get fast enough, the stack flattens: the model drives the app in real time and just emits the pixels. Jev's generative-UI demos are an early hint.
- On screen: Joon Lee on Cognition's SWE-1.7 at 1,000 tok/s: "an entirely different experience for staying in flow state." Florian Brand (@xeophon): "really addictive to use models at >200 tok/s."
- Token speed is a differentiator.
Fit the work to the engine.
- It's not about the strongest model or the biggest data centre any more. It's about matching each workload to whoever should do it.
- There's a long tail of cost savings here. Stop and think about the task, and you can cut costs drastically.
- Same million calls: $84 on a decision model, $18,000 on Opus 5.5. That's 200x+. Not every task can step down, but a lot can.
- That'll be an ongoing process of discovery.
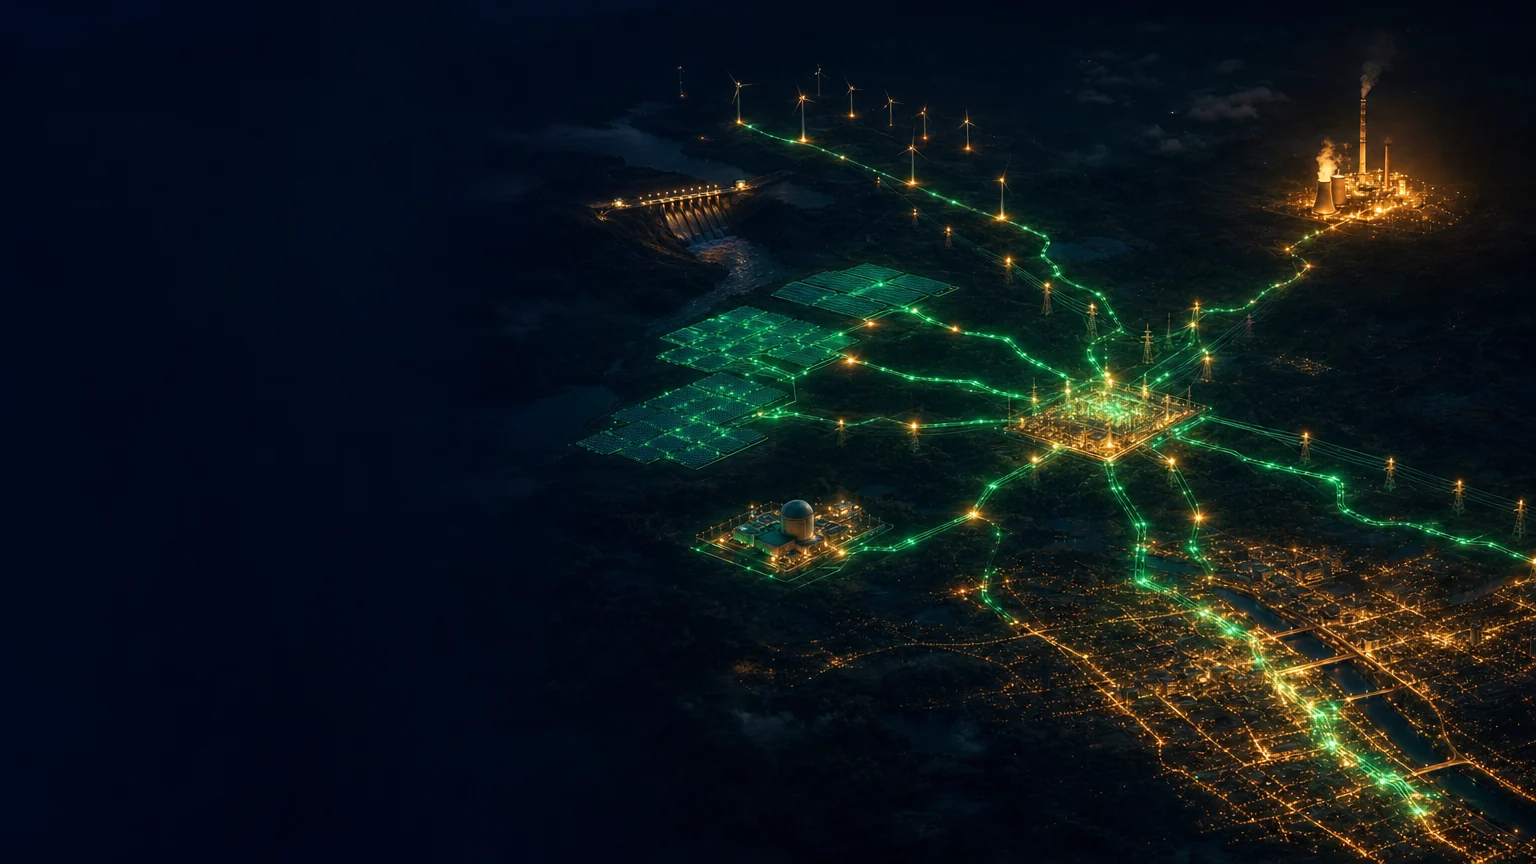
You don't pick the power station.
You plug in. The grid dispatches the cheapest source that can meet the load. The router does the same for AI.
OpenRouter already moves 600T+ tokens a month and ships routers that choose the model for you.
- OpenRouter started as an aggregator: one API in front of many LLMs. Best catalogue, and a big growth driver for inference providers.
- ~5T tokens a week in late 2025 → 600T+ a month now (company figures). openrouter/auto and the Jev Router already choose the model per request.
- The real story: it becomes the front door to AI. It routes and decomposes your request dynamically.
- Like the grid: you never choose which power station lights your kettle. The dispatcher runs cheap baseload first and fires the expensive peaker only when it has to. Frontier models are the peaker.
Own the generation,
not just the meter.
- As training your own models gets easier, sovereign AI becomes a much bigger deal. Routers on top of sovereign, multi-model stacks become infrastructure.
- Companies will turn away from sending all their data across borders to OpenAI and Anthropic. Coinbase is already doing it.
- Vertical example (Oct 12): Z.ai's GLM-Legal, built on GLM-5.3-Flash. 19.2% on Harvey LAB vs Claude Fable 5 at 11.3% (Z.ai's chart). Benchmarks span US and Chinese law. Limited beta, not open weights yet.
- The obvious next step: a law firm takes that and specialises it on its own practice area.
- The pitch on screen is the product we think wins.
Not one model.
The right one.
- Right-sizing is the new frontierSpecialists, fine-tunes and decision models take production work.
- The router becomes the front doorWhoever dispatches the request owns the customer.
- Speed is a feature1,000+ tok/s keeps you in flow. Fast beats smartest for most loops.
- Sovereign stacks are comingYour models, your hardware, your data.
- Wrap up: four things to watch. Questions.